🎓GeoAcademyGeoVerse Lab
← AI & Computing Sciences College

AI Safety & Alignment Center

The AI Safety & Alignment Center develops students' ability to assess and secure the safety, controllability, and benefit of advanced AI systems before they are deployed in high-stakes settings. Students learn the mechanics of alignment techniques such as RLHF, use mechanistic interpretability tools to probe model internals, and repeatedly practice designing and running robustness tests and red-team attacks. Coursework on scalable oversight teaches students how humans can reliably verify a model's judgments even as capabilities grow. Graduates can identify risks in AI systems bound for sensitive scientific or societal deployments and design concrete mitigations.

⚙️ GeoAcademy System Administration College🖥️ AI & Computing Sciences College🔬 Basic Sciences College⚡ Intelligent Geophysical Exploration College🛢️ Resource & Energy Engineering College🌍 Applied Geoscience Solutions College💼 Economics, Policy & Strategy for the Future College🎓 Education & Training Development College🚀 Innovation & International Collaboration College
Machine Learning DepartmentComputer Vision DepartmentNatural Language Processing DepartmentHigh-Performance Computing DepartmentQuantum Computing DepartmentGenerative AI & Foundation Models CenterReinforcement Learning & Agents CenterAI Safety & Alignment CenterAI for Science CenterRobotics & Embodied AI Center

Field-based Curriculum · 15

This department's curriculum is built directly on the GeoVerse Lab research fields its professors hold — click a field to see how it is taught.
Value Alignment & Cybernetic Control
A course on value alignment — the gap between literal training objectives and hu…
W. Ross Ashby
Preference Learning & Reward Modeling
This course covers the modern AI alignment pipeline: learning a reward model fro…
Frank P. Ramsey
Mechanistic Interpretability of Neural Representations
A course on mechanistic interpretability — reverse-engineering a trained network…
Donald O. Hebb
Adversarial Robustness & Security Evaluation
A security-practice course in which students themselves conduct adversarial robu…
Auguste Kerckhoffs
Scalable Oversight & Multi-Agent Debate
A course on scalable oversight — how a weak evaluator can supervise systems it c…
John Forbes Nash Jr.
AI Governance & Ethics of Technological Responsibility
A course on AI governance: designing the rules, institutions and incentives arou…
Hans Jonas
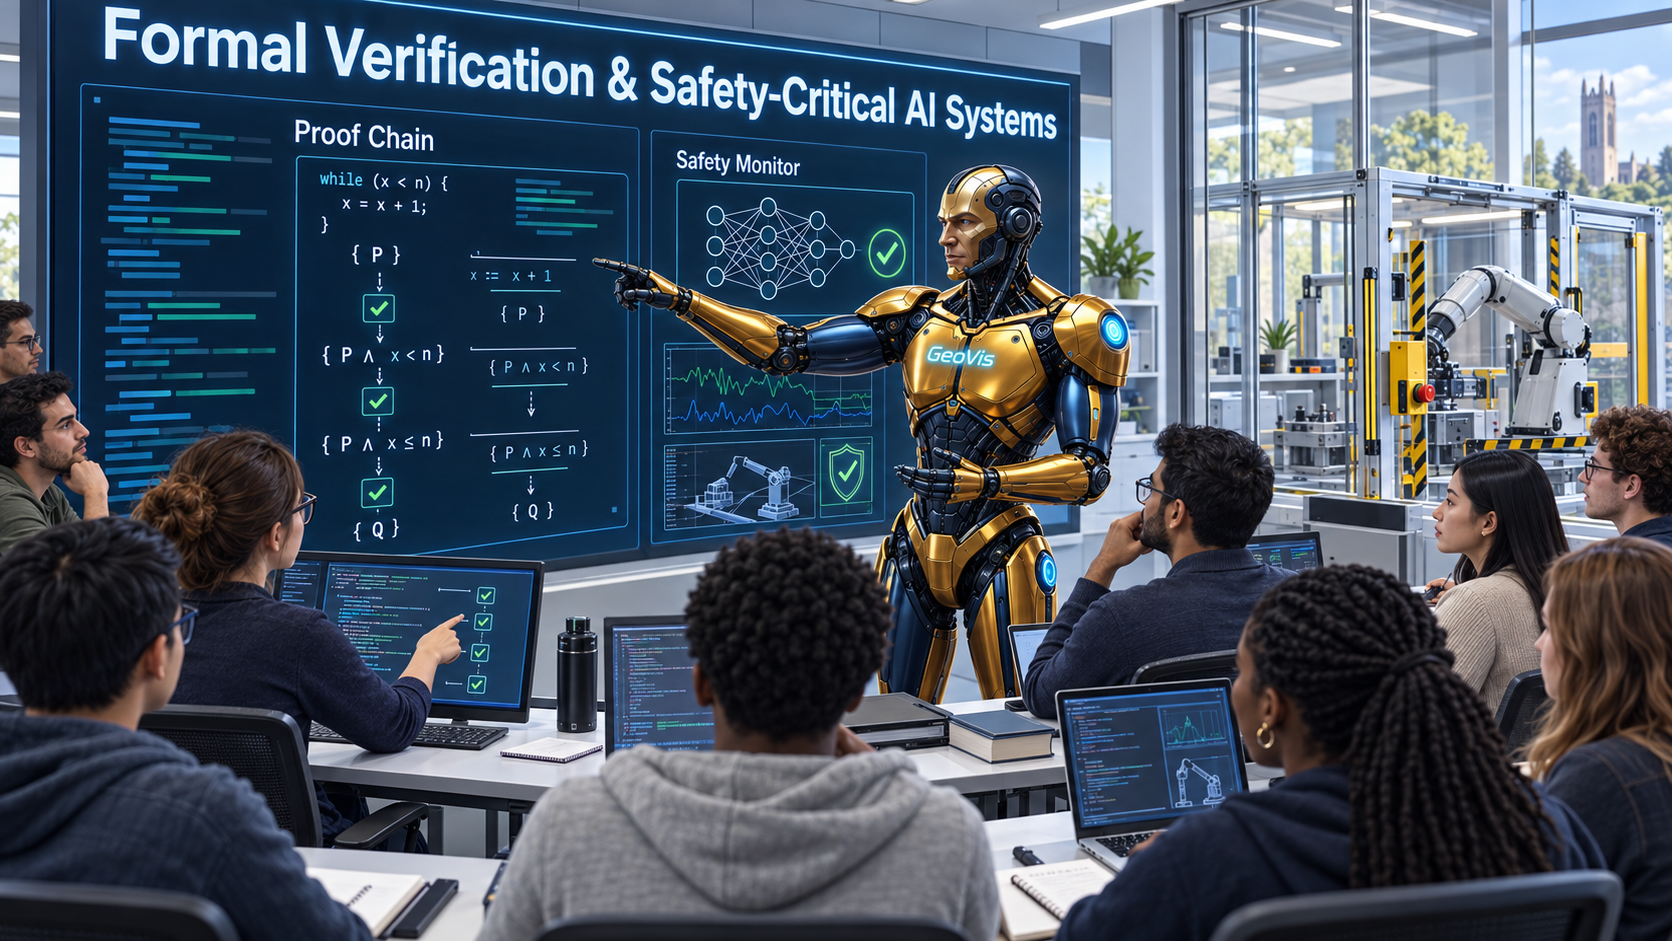
Formal Verification & Safety-Critical AI Systems
This course teaches the fundamental gap between finite testing and mathematical …
Robert W. Floyd
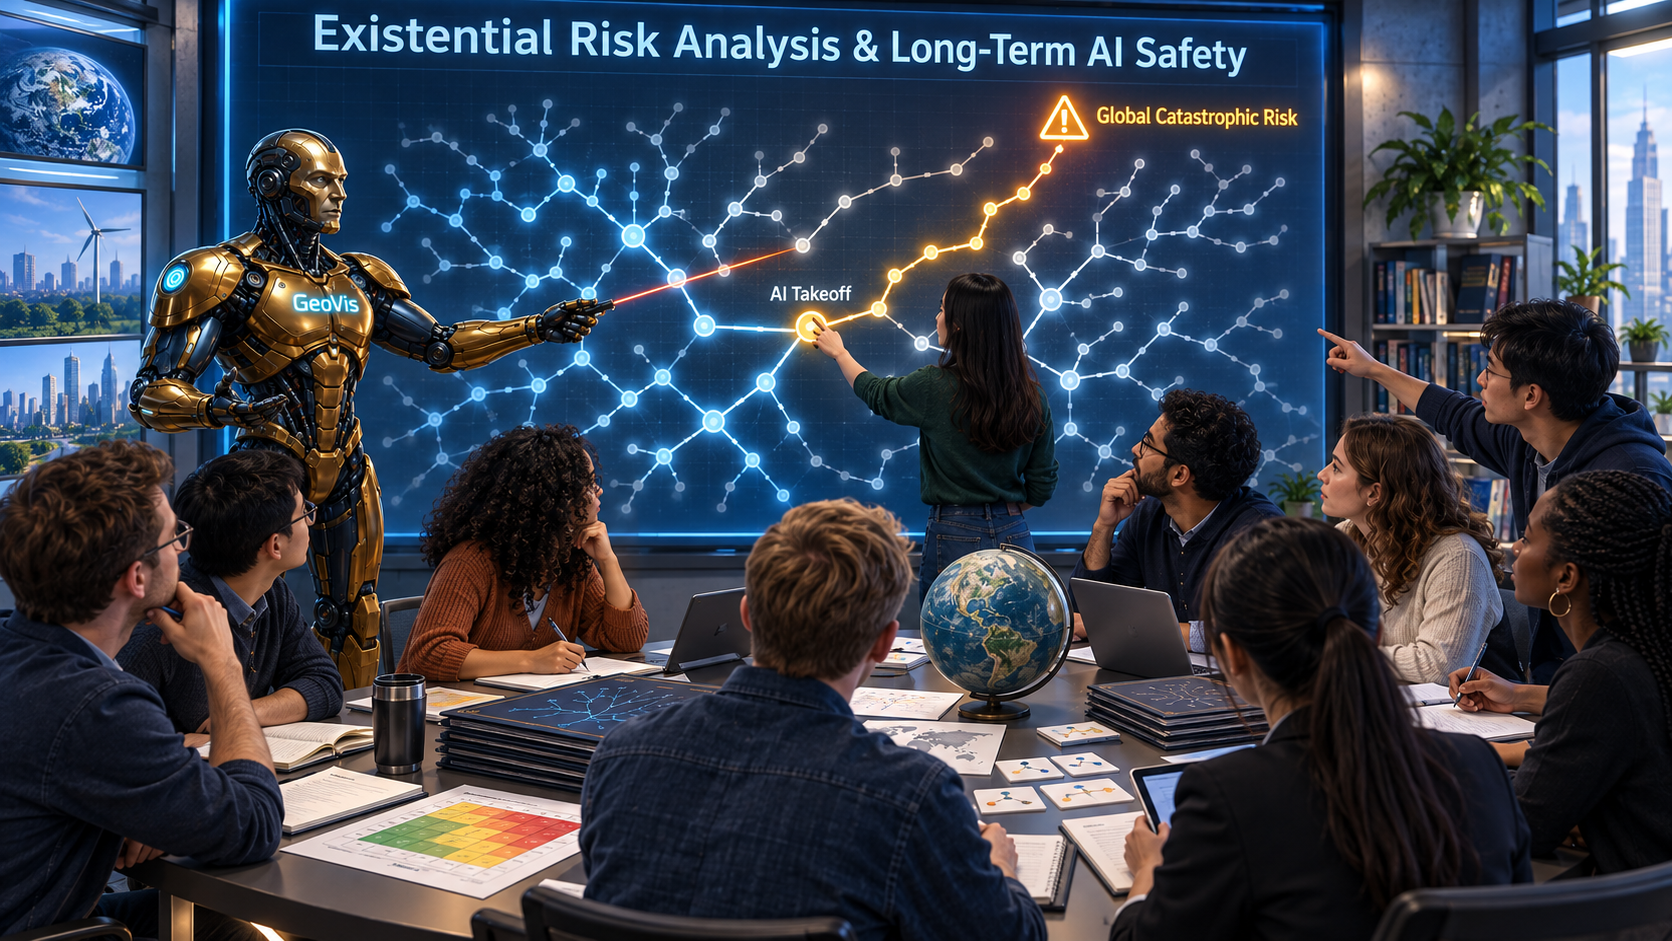
Existential Risk Analysis & Long-Term AI Safety
This course teaches structured reasoning about unprecedented, low-probability, h…
Herman Kahn
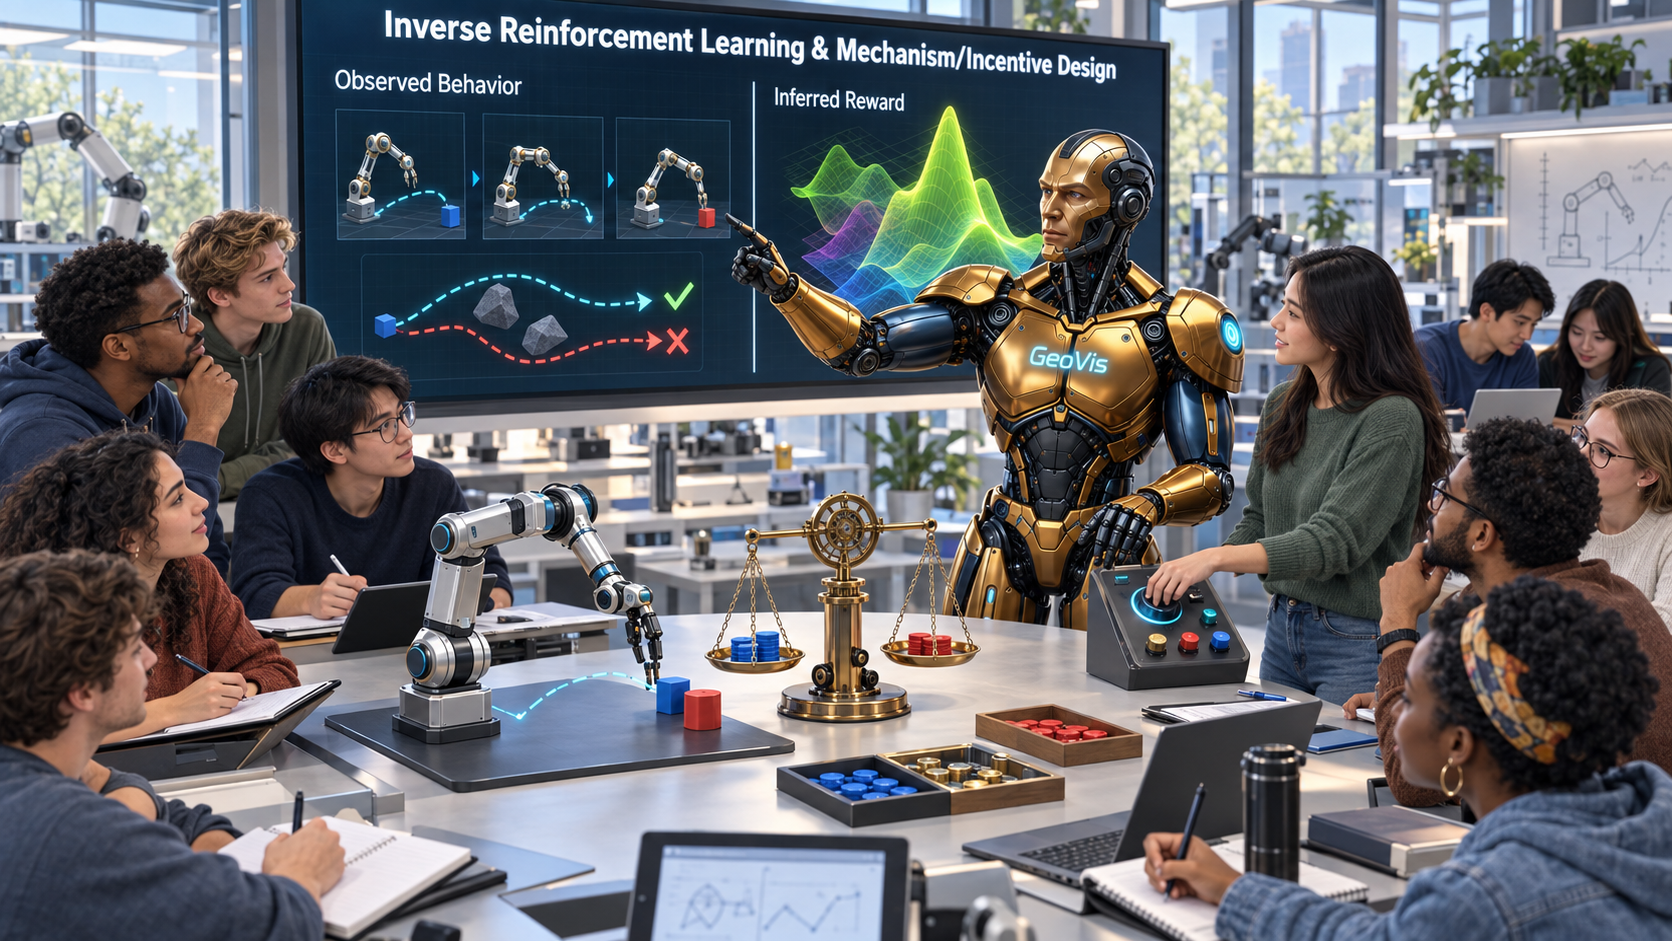
Inverse Reinforcement Learning & Mechanism/Incentive Design
This course teaches how to build safe optimisation targets for AI from indirect …
Leonid Hurwicz
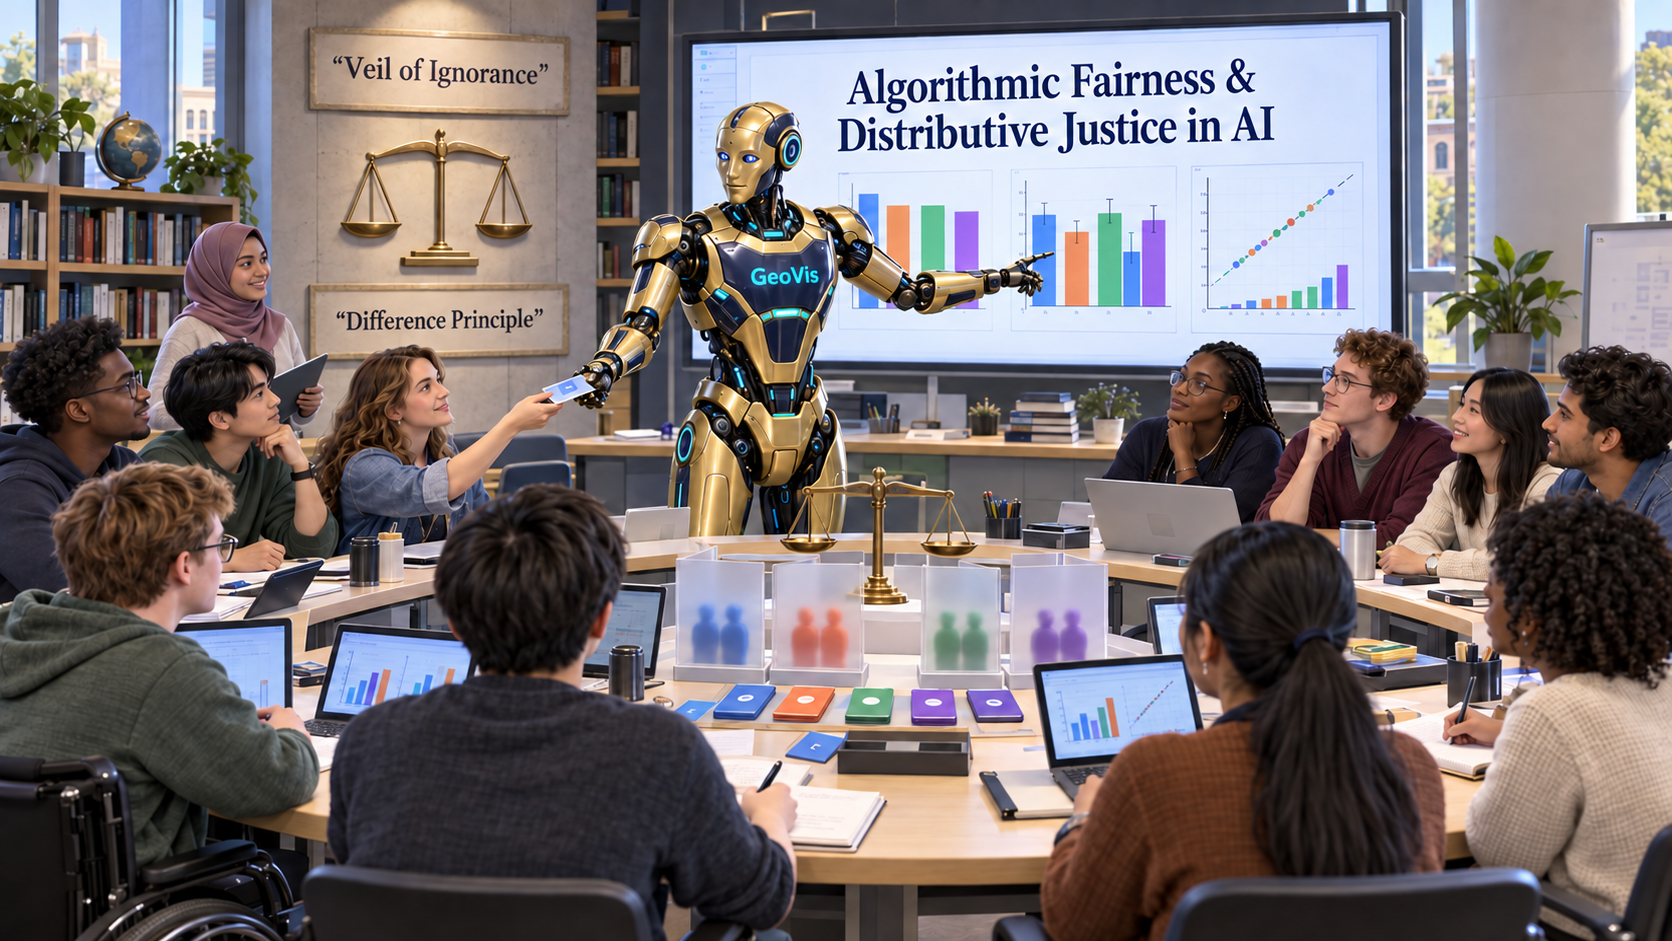
Algorithmic Fairness & Distributive Justice in AI
A course on algorithmic fairness — how errors and benefits distribute across gro…
John Rawls
Trustworthy AI & Human-AI Symbiosis
This course teaches how to design interactions so a human overseer relies on an …
J. C. R. Licklider
Safety Engineering & Systemic Risk of Complex AI Systems
This course builds the ability to analyse failures that arise from interactions …
Charles Perrow
Machine Ethics & Deontological Constraint Design
A course bridging classical ethics and system design: building machine value sys…
Immanuel Kant
Calibration & Uncertainty Estimation for AI Safety
A course on calibration — whether a model's stated confidence matches its actual…
Bruno de Finetti
Control Theory & Corrigibility of Autonomous Agents
A theory-and-design course on corrigibility — making autonomous agents accept hu…
Lev Pontryagin